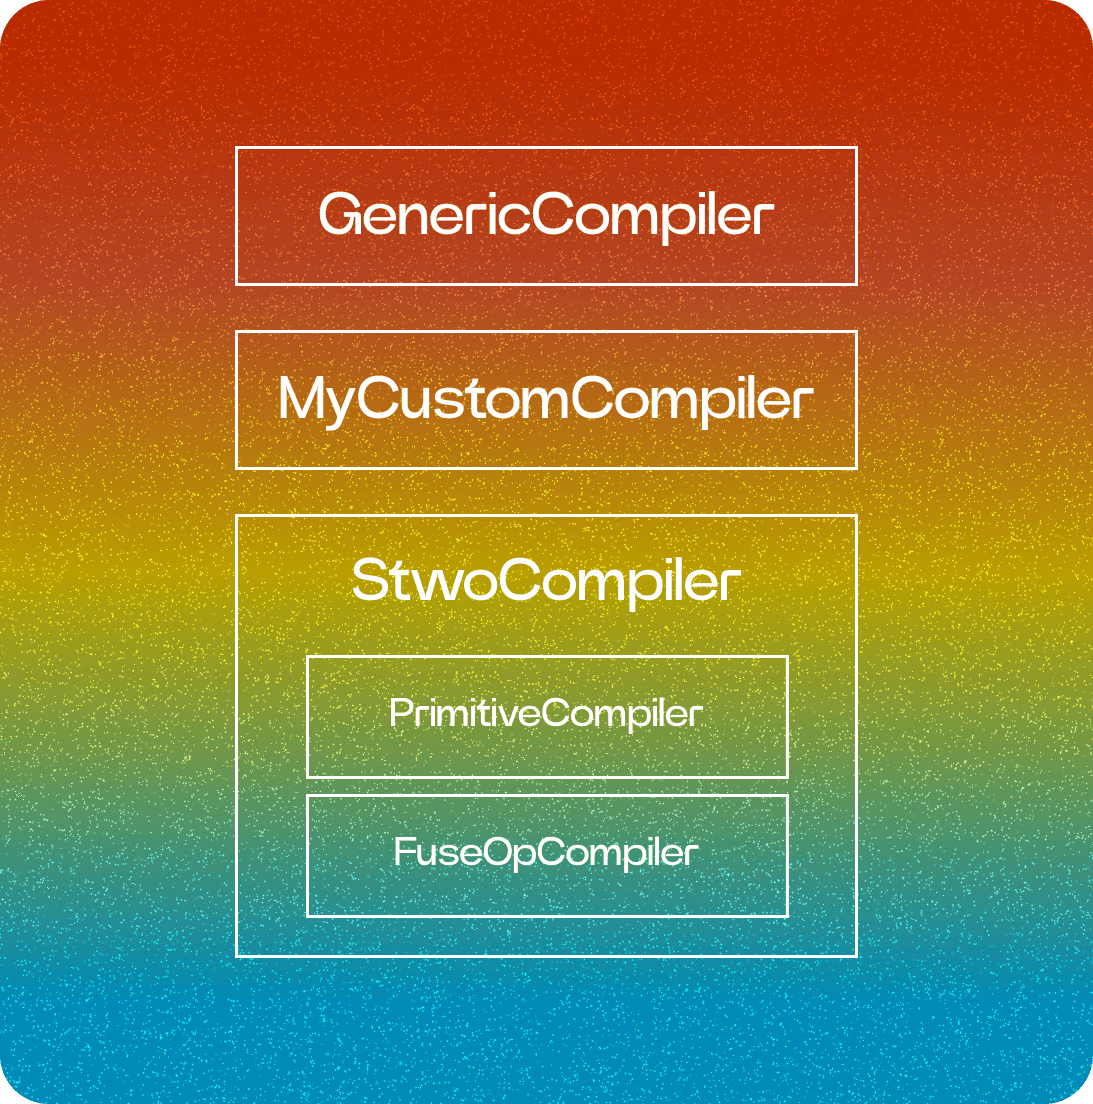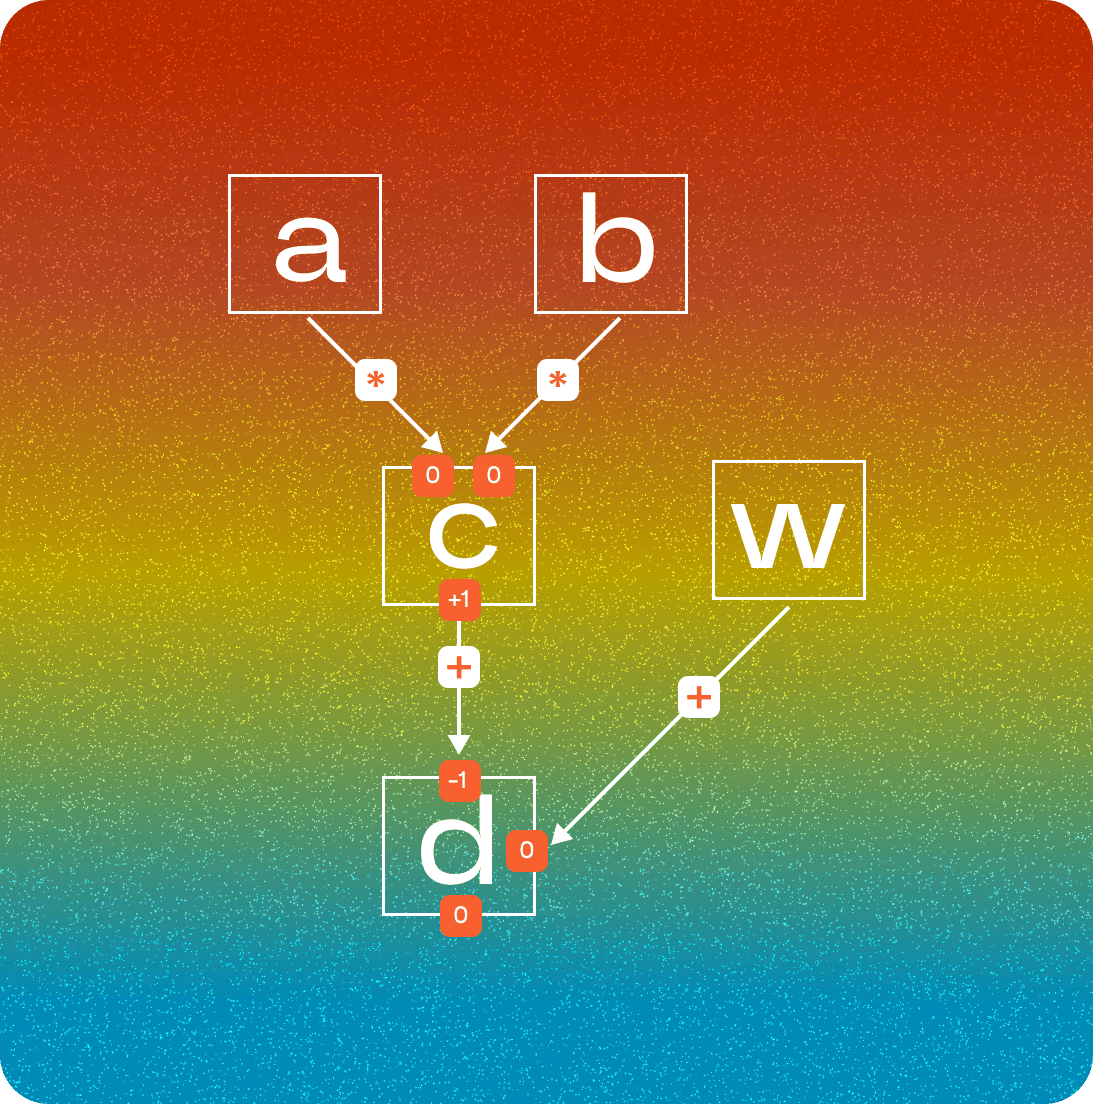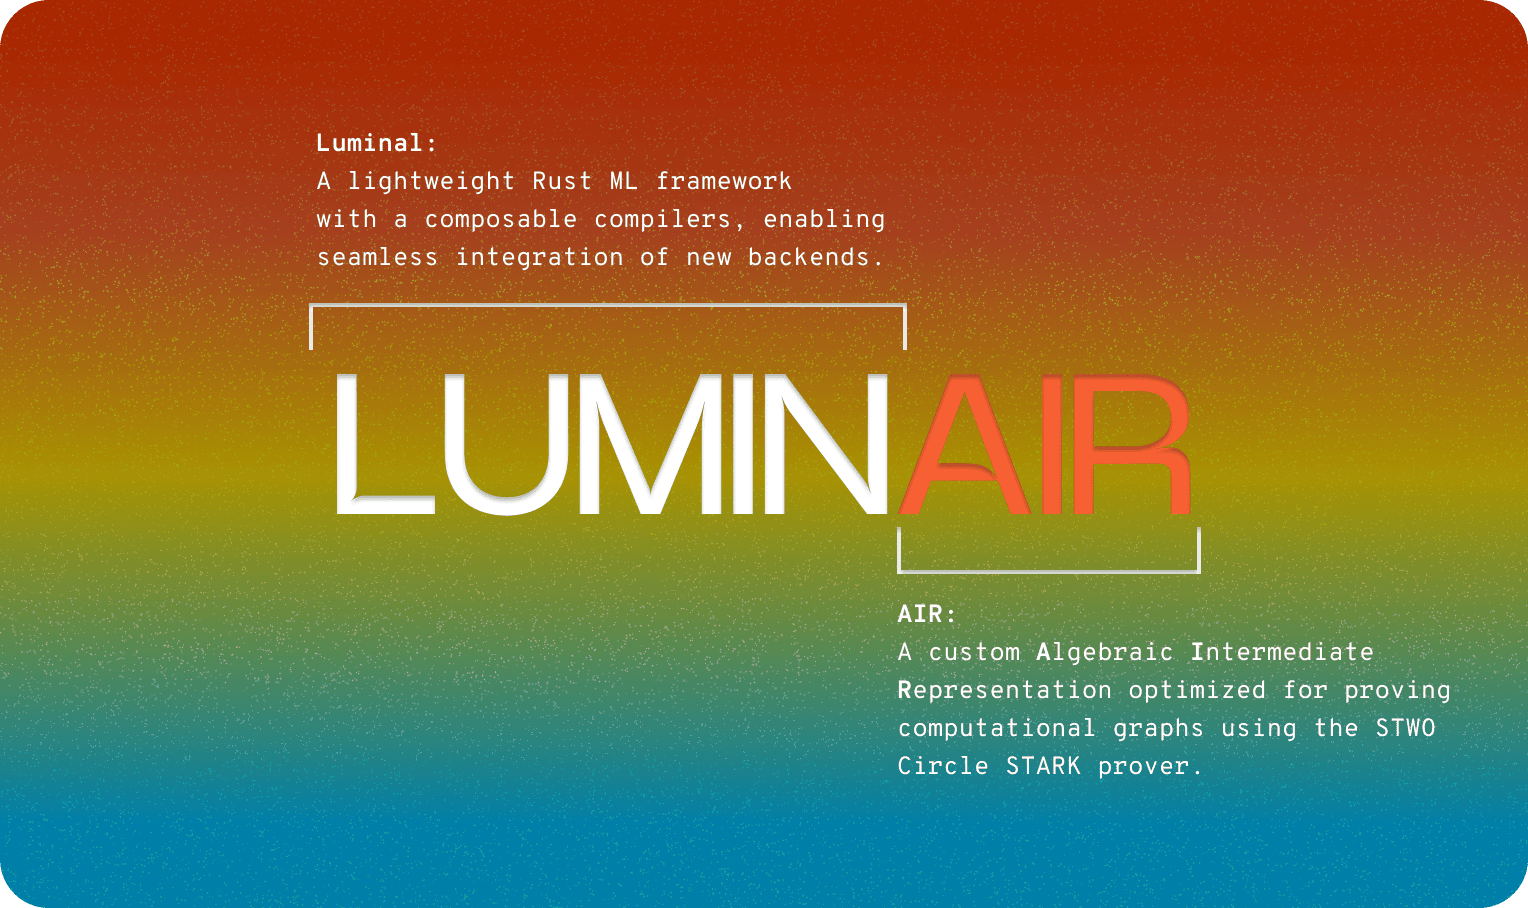
# Behind The Scenes Source: https://luminair.gizatech.xyz/behind-the-scenes Bridging Machine Learning and Zero-Knowledge Proofs **LuminAIR** leverages the strengths of two powerful frameworks: [Luminal](https://github.com/jafioti/luminal) and [Stwo](https://github.com/starkware-libs/stwo). * **Luminal** provides the foundation for our machine learning framework, expertly handling computational graphs and compilers. * **Stwo** serves as the constraint framework, enabling us to design an Algebraic Intermediate Representation (AIR) that is provable using Stwo’s compatible prover and verifier. # Luminal: A Minimalist Machine Learning Framework Luminal is a Rust-based machine learning framework, drawing inspiration from [Tinygrad](https://github.com/tinygrad/tinygrad). Its key feature is the use of composable compilers, which simplify the process of adding support for new backends. Luminal’s design philosophy centers around a minimal core, ensuring maintainability. At its heart, Luminal operates with just 11 primitive operators: * **Unary**: `Log2`, `Exp2`, `Sin`, `Sqrt`, `Recip` * **Binary**: `Add`, `Mul`, `Mod`, `LessThan` * **Other**: `SumReduce`, `MaxReduce`, `Contiguous` These ops are enough to support linear regression, convnets, transformers, etc. You might think that such a small set of operations would severely limit the library’s capabilities. However, Luminal overcomes this limitation through the strategic use of composable compilers. These compilers allow us to extend the functionality of the core by adding new operations and optimizations in a modular and isolated manner. For example, because the core library doesn’t handle specific devices, we can create compilers that replace the core operations with equivalent operations optimized for different hardware, such as CUDA GPUs or TPUs. In the context of LuminAIR, we use compilers to target ZK circuits. The beauty of this approach is that with only 11 core operations, the process of creating these specialized compilers becomes remarkably straightforward. Therefore, our work with LuminAIR involves leveraging Luminal’s composable compilers to develop efficient compilers specifically tailored for proving computational graphs using Zero Knowledge proofs. # AIR: A Custom Algebraic Intermediate Representation Proved with Stwo Stwo, developed by [Starkware](https://starkware.co/), represents the next generation of STARK provers. It incorporates the innovative [Circle STARK protocol](https://eprint.iacr.org/2024/278), along with a variety of other optimizations. Stwo unlocks the potential of the highly efficient prime field M31, benefiting the entire ZK-proof ecosystem. We are leveraging Stwo framework to define constraints for our AIR. LuminAIR designs a compiler that swaps each operation in the graph with its corresponding component in our AIR, enabling the generation of C-STARK proofs for the computational graph. While, in theory, we could support other ZK backends in the future by developing new compilers, our primary focus for now is on Stwo. # Compilers Source: https://luminair.gizatech.xyz/concepts/compilers Core transformations of the computational graph. A fundamental principle of LuminAIR is its reliance on ahead-of-time (AOT) compilation. By pushing all computations to compile time, LuminAIR eliminates runtime overhead, ensuring that every operation in the computational graph is static and optimized before execution. When you write an expression like `x + y` in LuminAIR, no computation happens immediately. Instead: * The operation is recorded in a directed acyclic computation graph. * Actual computation occurs only when `graph.gen_trace()` is executed. This approach, akin to lazy execution, allows LuminAIR to treat entire ML models as static computation graphs. ## Why AOT Compilation? By fully representing ML models as static computation graphs, compilers have global knowledge of the entire model. This allows for: 1. **Advanced Optimizations**: Compilers can perform tasks like operator fusion, backend-specific optimizations, and linking operations to their AIR equivalents. 2. **Separation of Concerns**: All complexity is pushed to compile time, leaving runtime execution lightweight and efficient. ## How LuminAIR Compilers Work Compilers in LuminAIR are modular and stackable, meaning multiple compilers can be applied sequentially to transform the computation graph. Each compiler focuses on a specific optimization task. ### Default Compilers Provided by LuminAIR 1. **GenericCompiler** * Developed by [Luminal](https://github.com/jafioti/luminal), it applies backend-agnostic optimizations. * Includes techniques like Common Subexpression Elimination [(CSE)](https://en.wikipedia.org/wiki/Common_subexpression_elimination). to eliminate redundant computations. * Should always run before any specialized compilers. 2. **StwoCompiler** * A specialized compiler designed for proving computational graphs using the [Stwo](https://github.com/starkware-libs/stwo) prover. * Replaces operations in the graph with their equivalent components in the AIR. `StwoCompiler` currently includes `PrimitiveCompiler`. It maps primitive operators (e.g., `Add`, `Mul`) to their corresponding AIR components. ```rust theme={null} pub type StwoCompiler = (op::prim::PrimitiveCompiler,); ``` In the future, `StwoCompiler` will include additional sub-compilers, such as `FuseOpCompiler`, focuses on fusing multiple primitive operations into optimized composite operators. ### Customizing Compilers for Specific Use Cases LuminAIR supports custom compilers, designed by users, that can be stacked alongside default ones to address specific use cases. ```rust theme={null} cx.compile(<(GenericCompiler, MyCustomCompiler, StwoCompiler)>::default(), &mut e); ``` Here: * `GenericCompiler` applies general optimizations. * `MyCustomCompiler` implements user-defined transformations for a specific task. * `StwoCompiler` prepares the graph for proof generation using the Stwo prover. # GraphTensor Source: https://luminair.gizatech.xyz/concepts/graph-tensor The high-level interface for writing ML code, checked at compile time. **GraphTensors** are a fundamental part of LuminAIR, serving as references to nodes within the computational graph. They provide a high-level interface for defining machine learning models and operations, ensuring that all computations are checked at compile time. # Creating a GraphTensor To get started, you can create a `GraphTensor` by initializing a graph and adding tensor nodes: ```rust theme={null} let mut cx = Graph::new(); // Initialize a new computational graph let a: GraphTensor> = cx.tensor(); // Create a new tensor node in the graph ``` Here: * `Graph::new()` initializes a new computational graph. * `GraphTensor>` represents a tensor node with metadata about its shape (in this case, rank-1 with size 3). # Performing Operations with GraphTensors Once you have created `GraphTensors`, you can perform various linear algebra operations, similar to libraries like [PyTorch](https://pytorch.org/): ```rust theme={null} let b = a.exp().sqrt(); // Apply exponentiation and square root operations let c = b + a; // Add tensors b and a ``` Operations like `b + a` do not consume the original tensors (`a` and `b`). Both remain available for reuse in subsequent operations. This is made possible because `GraphTensor` is a lightweight tracking structure that implements the `Copy` trait. This design allows operations on `GraphTensor` to construct a computational graph without immediate execution, so no values are assigned to the `GraphTensor` at this stage. Actual computations are postponed until `cx.gen_trace()` is invoked, which enables the compiler to optimize the execution process effectively. For more details on how to build, run, and prove graphs, check out this [guide](/quick-start). # Integrity Source: https://luminair.gizatech.xyz/concepts/integrity What do we prove? LuminAIR’s primary goal is to cryptographically demonstrate that a computational graph has been executed correctly. This proof allows verifiers to validate the integrity of the computation using significantly fewer resources than re-executing the graph. The underlying technology enabling this is [STARKs](https://starkware.co/stark/) (Scalable Transparent Arguments of Knowledge), which ensures computational integrity through a transparent, scalable, and post-quantum secure proof system. STARKs are based on transforming computations into algebraic representations, enabling the creation of cryptographic proofs of correctness. Here’s an overview of how they work: 1. **Arithmetization** * The first step in STARKs is arithmetization, where a computational problem is converted into an algebraic form. This involves expressing the computation as a sequence of operations over finite fields. * The computation is represented as an Algebraic Intermediate Representation (AIR), which defines constraints as polynomials over trace cells. These constraints ensure that the computation satisfies certain properties. 2. **Execution Trace** * During execution, the state of the computation at each step is recorded in an algebraic execution trace. This trace consists of tuples of values (or “registers”) from a finite field. * The trace captures the evolution of the computation, step by step, and serves as the foundation for constructing proofs. 3. **Low-Degree Polynomials** * The prover interpolates the execution trace into low-degree polynomials. These polynomials encode the entire computation in a compact mathematical form. * The AIR constraints are then expressed as operations on these polynomials, ensuring that only valid computations produce low-degree polynomials. 4. **Proof Generation** Using techniques like [FRI](https://aszepieniec.github.io/stark-anatomy/fri.html), the prover generates a cryptographic proof that certifies: * The algebraic execution trace satisfies all AIR constraints. * The polynomials derived from the trace are indeed low-degree. This proof is succinct, meaning it is much smaller than the original computation. 5. **Verification** * The verifier checks the proof probabilistically by sampling specific points on the polynomials. If these points satisfy the constraints, it is overwhelmingly likely that the entire computation was executed correctly. * This process requires far fewer resources than re-executing the original computation, making STARKs highly efficient for verification. # Using STARKs to Prove Computational Graphs ### Mapping Computational Graph Nodes to AIR Components In LuminAIR, computational graphs are transformed into AIR constraints and executed to generate an algebraic execution trace. Each operator corresponds to a distinct AIR component, which has its own set of local constraints. These constraints ensure that each operation in the graph is executed correctly. ### Ensuring Data Flow Integrity Between Nodes While each AIR component verifies its local operation, it is equally important to ensure proper data flow between nodes in the computational graph. Specifically, the output of one node must match the input of another node. This consistency is enforced using the [LogUp](https://eprint.iacr.org/2022/1530?ref=blog.lambdaclass.com) lookup argument protocol, which establishes a system of relations between tensor values. **Output Yields** (Positive Multiplicity) * When a node produces an output that will be consumed by other nodes, its multiplicity equals the number of consumers. * This indicates that the value is “yielded” for use elsewhere in the graph. **Input Consumes** (Negative Multiplicity) * When a node receives an input from another node, its multiplicity is `-1`. * This signifies that the value is “consumed” by the operation. **Special Cases** (Zero Multiplicity) * Graph Inputs (Initializers): Tensors that serve as initial inputs to the graph have zero multiplicity because they are not consumed by any prior operation. * Graph Outputs (Final Results): Tensors that represent final outputs of the graph also have zero multiplicity since they are not yielded to subsequent operations. # Operators Source: https://luminair.gizatech.xyz/concepts/operators Core Building Blocks of LuminAIR In LuminAIR, operators represent the fundamental operations that a computational graph executes. Each operator is associated with an AIR component, which ensures integrity during proof generation. # Primitive Operators LuminAIR adopts a RISC-style architecture for its operators. LuminAIR supports a minimal set of 11 primitive operators. These operators are sufficient to implement a wide range of machine learning models, such as linear regression, convolutional networks, and transformers. | Operator | Status | | ------------ | ------ | | `Log2` | ✅ | | `Exp2` | ✅ | | `Sin` | ✅ | | `Sqrt` | ✅ | | `Recip` | ✅ | | `Add` | ✅ | | `Mul` | ✅ | | `Mod` | ✅ | | `LessThan` | ✅ | | `SumReduce` | ✅ | | `MaxReduce` | ✅ | | `Contiguous` | ✅ | These primitive operators are handled by the `PrimitiveCompiler`, a subset of the `StwoCompiler`. Each operator is mapped to its corresponding AIR component during compilation, ensuring compatibility with the proof generation process. # High-Level Operators While the primitive operators cover a wide range of models, they may not always be the most efficient choice. Complex operations in machine learning often require multiple primitive operators, leading to large graphs with many nodes. This can slow down both execution and proof generation. To address this, LuminAIR plans to introduce fused operators in future phases (see [Roadmap](/more/roadmap)). These fused operators will combine multiple primitives into single optimized operations, reducing graph complexity and improving performance. The exact list of fused operators is still under development, but priority will be given to commonly used ML operations such as MatMul, SoftMax or ReLU. # Prove & Verify Source: https://luminair.gizatech.xyz/concepts/prove-verify Ensuring Computational Integrity with LuminAIR. LuminAIR’s primary objective is to cryptographically prove that a computational graph has been executed correctly. This proof allows verifiers to validate the computation’s integrity using significantly fewer resources than re-executing the graph. The process is powered by the `StwoCompiler` and the Stwo prover, enabling efficient proof generation and verification. # What is Stwo? [Stwo](https://github.com/starkware-libs/stwo) is a next-generation implementation of the [Circle STARK](https://eprint.iacr.org/2024/278) protocol, written in Rust. Developed by Starkware, it is an ultra-efficient ZK prover designed for scalable succinct proofs. Stwo unlocks the potential of the highly efficient prime field M31, benefiting the entire ZK-proof ecosystem. # How LuminAIR Leverages Stwo The `StwoCompiler` plays a critical role in transforming and optimizing computational graphs. It assigns each operator in the graph to its corresponding AIR component, preparing the graph for proof generation using the Stwo prover. # LuminAIR Prover The LuminAIR prover integrates directly with the Stwo library to: 1. Implement AIR components for each operator in the computational graph. 2. Generate an execution trace, which records the state of each operation during execution. 3. Produce succinct proofs. ### SIMD Backend for Parallelization The LuminAIR prover currently supports a SIMD backend, allowing parallelized proof generation on devices equipped with SIMD capabilities. For smaller traces or devices without SIMD support, a fallback to `CpuBackend` ensures compatibility. ### Future Plans: GPU Acceleration In the roadmap, LuminAIR plans to support [Icicle-Stwo](https://github.com/ingonyama-zk/icicle-stwo), an implementation of Stwo by [Ingonyama](https://www.ingonyama.com/) that enables CUDA-based GPU acceleration. This will significantly enhance proof generation speed for large-scale computation # LuminAIR Verifier The LuminAIR verifier, written in Rust, validates proofs generated by the prover. It ensures: 1. The LogUp sum is correct (Cf. [integrity section](/concepts/integrity)). 2. The proof satisfies all constraints defined by the AIR components. ### Future Plans To expand its trustlessness, LuminAIR plans to implement additional verifier backends: 1. **WASM Verifier**: A WebAssembly implementation will allow proofs to be verified directly in web browsers, enabling trustless verification by a client. 2. **Onchain Verification**: * Implementing the verifier as a [Cairo](https://www.cairo-lang.org/) program verified onchain. * Using [AVSs](https://app.eigenlayer.xyz/avs) like [Aligned Layer](https://alignedlayer.com/) to leverage Ethereum’s crypto-economic security. # Shape Tracking Source: https://luminair.gizatech.xyz/concepts/shape-tracking Compile-time shape tracking When working with a [GraphTensor](/concepts/graph-tensor) in LuminAIR, you may notice that its type includes a specific generic parameter. This parameter encodes the tensor’s shape directly at the type level, enabling compile-time shape tracking. # What Does the Shape Parameter Represent? Consider the following example: ```rust theme={null} let a: GraphTensor> = cx.tensor(); ``` Here, `R1<3>` is the shape parameter of the `GraphTensor`. Let’s break it down: * `R1`: Represents the rank of the tensor, which is the number of dimensions it has. In this case, `R1` denotes a rank-1 tensor (a one-dimensional tensor). * `<3>`: Specifies the size of the tensor along its single dimension. Here, `<3>` means the tensor contains 3 elements Together, `R1<3>` defines a one-dimensional tensor with 3 elements—a 3-dimensional vector. # How Does Shape Tracking Work? The shape parameter (`R1`) is implemented as a type alias for `(Const,)`, where `Const` is a compile-time constant representing the size of the tensor. This design allows Rust to enforce tensor shapes at compile time, ensuring that: 1. **Shape Mismatches Are Caught Early**: Tensor operations are only allowed between tensors with compatible shapes. 2. **No Runtime Shape Calculations**: Since shapes are encoded in types, there’s no need to compute or validate shapes during execution. # Implementation Guide Source: https://luminair.gizatech.xyz/contribute/add-ops Adding New Operators to LuminAIR Welcome to this comprehensive guide on implementing new operators in LuminAIR! This tutorial will walk you through the entire process of adding a new computational operator, using the `Add` operator as our running example. By the end, you'll understand the architecture, components, and steps needed to contribute to LuminAIR by adding new operators. We assume that you have read the LuminAIR documentation before following this tutorial. # Introduction to LuminAIR Architecture LuminAIR is a framework that combines machine learning computations with STARK proofs to ensure verifiable computation. The system is built on several key components: 1. **Graph System:** Based on Luminal, it represents computational operations as a directed graph. 2. **AIR Components:** Each operation type has a corresponding Arithmetic Intermediate Representation (AIR) that defines mathematical constraints. 3. **Trace Tables:** Execution traces that capture the computation steps for each operation. 4. **Prover/Verifier:** Uses Stwo's Circle STARK system to generate and verify proofs of computation. These components work together to enable verifiable computation: a prover executes the computation graph, generates traces and proofs, which can then be verified by a verifier without re-executing the entire computation. # Understanding Fixed-Point Arithmetic LuminAIR uses fixed-point arithmetic for all operations. This is because STARK proofs operate in finite fields, which don't naturally represent floating-point numbers. We implemented a fixed-point library called [NumerAIR](https://github.com/gizatechxyz/NumerAir) that provides the fixed-point implementation used within LuminAIR. In our system: * Fixed-point numbers uses by default a 12-bit scale factor (defined by `DEFAULT_SCALE` in NumerAIR). * Operations need to account for this scale factor. * Field elements come from the `M31` field, which has a prime modulus of `2^31-1`. For example, the real number `1.5` would be represented as `1.5 * 2^12 = 6144` in our fixed-point format. # Overview of Implementing a New Operator To implement a new operator in LuminAIR, you need to create several components: 1. **TraceTable Definition:** Define the structure for storing execution traces. 2. **AIR Component:** Define constraints that verify the operation's correctness. 3. **Operator Implementation:** Create the logic that executes the operation and generates traces. 4. **Interaction Trace:** Generate the traces needed for LopUp arguments. 5. **Graph Integration:** Connect the operator to LuminAIR's graph system. Let's walk through each of these components in detail, using the `Add` operator as our example. # Implementing the Operator TraceTable The first step is defining the structure for storing the execution trace of your operator. This is done by creating a table that holds all the values needed for the constraint system. For the `Add` operator, we define `AddTraceTable` and `AddTraceTableRow` in `crates/air/src/components/add/table.rs`: ```rust theme={null} /// Represents the trace for the Add component #[derive(Debug, Default, PartialEq, Eq, Clone)] pub struct AddTraceTable { /// A vector of AddTraceTableRow representing the table rows pub table: Vec, } /// Represents a single row of the AddTraceTable #[derive(Debug, Default, PartialEq, Eq, Clone)] pub struct AddTraceTableRow { pub node_id: BaseField, pub lhs_id: BaseField, pub rhs_id: BaseField, pub idx: BaseField, pub is_last_idx: BaseField, pub next_node_id: BaseField, pub next_lhs_id: BaseField, pub next_rhs_id: BaseField, pub next_idx: BaseField, pub lhs: BaseField, pub rhs: BaseField, pub out: BaseField, pub lhs_mult: BaseField, pub rhs_mult: BaseField, pub out_mult: BaseField, } ``` Each row in the table represents one step in the execution of the addition operation: * `node_id`, `lhs_id`, `rhs_id`: Identifiers for the nodes in the computation graph. * `idx`: The current index in the tensor. * `is_last_idx`: A flag (0 or 1) indicating if this is the last element. * `next_*` fields: Values for the next row, used for transition constraints. * `lhs`, `rhs`, `out`: The left operand, right operand, and result values. * `lhs_mult`, `rhs_mult`, `out_mult`: Multiplicity values for the lookup argument. You'll also need to implement the `trace_evaluation` method on `AddTraceTable`, which converts the table into a format that can be used for commitment and proofs: ```rust theme={null} impl AddTraceTable { /// Transforms the [`AddTraceTable`] into [`TraceEval`] to be commited /// when generating a STARK proof. pub fn trace_evaluation(&self) -> Result<(TraceEval, AddClaim), TraceError> { let n_rows = self.table.len(); if n_rows == 0 { return Err(TraceError::EmptyTrace); } // Calculate log size let log_size = calculate_log_size(n_rows); // Calculate trace size let trace_size = 1 << log_size; // Create columns let mut node_id = BaseColumn::zeros(trace_size); let mut lhs_id = BaseColumn::zeros(trace_size); let mut rhs_id = BaseColumn::zeros(trace_size); let mut idx = BaseColumn::zeros(trace_size); let mut is_last_idx = BaseColumn::zeros(trace_size); let mut next_node_id = BaseColumn::zeros(trace_size); let mut next_lhs_id = BaseColumn::zeros(trace_size); let mut next_rhs_id = BaseColumn::zeros(trace_size); let mut next_idx = BaseColumn::zeros(trace_size); let mut lhs = BaseColumn::zeros(trace_size); let mut rhs = BaseColumn::zeros(trace_size); let mut out = BaseColumn::zeros(trace_size); let mut lhs_mult = BaseColumn::zeros(trace_size); let mut rhs_mult = BaseColumn::zeros(trace_size); let mut out_mult = BaseColumn::zeros(trace_size); // Fill columns for (vec_row, row) in self.table.iter().enumerate() { node_id.set(vec_row, row.node_id); lhs_id.set(vec_row, row.lhs_id); rhs_id.set(vec_row, row.rhs_id); idx.set(vec_row, row.idx); is_last_idx.set(vec_row, row.is_last_idx); next_node_id.set(vec_row, row.next_node_id); next_lhs_id.set(vec_row, row.next_lhs_id); next_rhs_id.set(vec_row, row.next_rhs_id); next_idx.set(vec_row, row.next_idx); lhs.set(vec_row, row.lhs); rhs.set(vec_row, row.rhs); out.set(vec_row, row.out); lhs_mult.set(vec_row, row.lhs_mult); rhs_mult.set(vec_row, row.rhs_mult); out_mult.set(vec_row, row.out_mult); } for i in self.table.len()..trace_size { is_last_idx.set(i, BaseField::one()); } // Create domain let domain = CanonicCoset::new(log_size).circle_domain(); // Create trace let mut trace = Vec::with_capacity(AddColumn::count().0); trace.push(CircleEvaluation::new(domain, node_id)); trace.push(CircleEvaluation::new(domain, lhs_id)); trace.push(CircleEvaluation::new(domain, rhs_id)); trace.push(CircleEvaluation::new(domain, idx)); trace.push(CircleEvaluation::new(domain, is_last_idx)); trace.push(CircleEvaluation::new(domain, next_node_id)); trace.push(CircleEvaluation::new(domain, next_lhs_id)); trace.push(CircleEvaluation::new(domain, next_rhs_id)); trace.push(CircleEvaluation::new(domain, next_idx)); trace.push(CircleEvaluation::new(domain, lhs)); trace.push(CircleEvaluation::new(domain, rhs)); trace.push(CircleEvaluation::new(domain, out)); trace.push(CircleEvaluation::new(domain, lhs_mult)); trace.push(CircleEvaluation::new(domain, rhs_mult)); trace.push(CircleEvaluation::new(domain, out_mult)); assert_eq!(trace.len(), AddColumn::count().0); Ok((trace, AddClaim::new(log_size))) } } ``` # Implementing the AIR Component The AIR component defines the constraints that verify the correctness of the operation. For the `Add` operator, the AIR implementation is in `crates/air/src/components/add/component.rs`: ```rust theme={null} pub struct AddEval { log_size: u32, lookup_elements: NodeElements, } impl FrameworkEval for AddEval { /// Evaluates the AIR constraints for the addition operation. fn evaluate(&self, mut eval: E) -> E { // IDs let node_id = eval.next_trace_mask(); // ID of the node in the computational graph. let lhs_id = eval.next_trace_mask(); // ID of first input tensor. let rhs_id = eval.next_trace_mask(); // ID of second input tensor. let idx = eval.next_trace_mask(); // Index in the flattened tensor. let is_last_idx = eval.next_trace_mask(); // Flag if this is the last index for this operation. // Next IDs for transition constraints let next_node_id = eval.next_trace_mask(); let next_lhs_id = eval.next_trace_mask(); let next_rhs_id = eval.next_trace_mask(); let next_idx = eval.next_trace_mask(); // Values for consistency constraints let lhs_val = eval.next_trace_mask(); // Value from first tensor at index. let rhs_val = eval.next_trace_mask(); // Value from second tensor at index. let out_val = eval.next_trace_mask(); // Value in output tensor at index. // Multiplicities for interaction constraints let lhs_mult = eval.next_trace_mask(); let rhs_mult = eval.next_trace_mask(); let out_mult = eval.next_trace_mask(); // ┌─────────────────────────────┐ // │ Consistency Constraints │ // └─────────────────────────────┘ // The is_last_idx flag is either 0 or 1. eval.add_constraint(is_last_idx.clone() * (is_last_idx.clone() - E::F::one())); // The output value must equal the sum of the input values. eval.eval_fixed_add(lhs_val.clone(), rhs_val.clone(), out_val.clone()); // ┌────────────────────────────┐ // │ Transition Constraints │ // └────────────────────────────┘ // If this is not the last index for this operation, then: // 1. The next row should be for the same operation on the same tensors. // 2. The index should increment by 1. let not_last = E::F::one() - is_last_idx; // Same node ID eval.add_constraint(not_last.clone() * (next_node_id - node_id.clone())); // Same tensor IDs eval.add_constraint(not_last.clone() * (next_lhs_id - lhs_id.clone())); eval.add_constraint(not_last.clone() * (next_rhs_id - rhs_id.clone())); // Index increment by 1 eval.add_constraint(not_last * (next_idx - idx - E::F::one())); // ┌─────────────────────────────┐ // │ Interaction Constraints │ // └─────────────────────────────┘ eval.add_to_relation(RelationEntry::new( &self.lookup_elements, lhs_mult.into(), &[lhs_val, lhs_id], )); eval.add_to_relation(RelationEntry::new( &self.lookup_elements, rhs_mult.into(), &[rhs_val, rhs_id], )); eval.add_to_relation(RelationEntry::new( &self.lookup_elements, out_mult.into(), &[out_val, node_id], )); eval.finalize_logup(); eval } } ``` Here, the AIR of the `Add` component defines three types of constraints: 1. **Consistency Constraints:** Ensure each row's values are valid (output equals the sum of inputs). 2. **Transition Constraints:** Ensure the relationship between consecutive rows is valid (e.g., for tensor operations that span multiple rows). 3. **Interaction Constraints:** We are using LogUp protocol here to constraining dataflow of the inputs/output. Ensuring that the input of a node equals the output of a precedent node. For the `Add` operator, the key constraint is the `eval_fixed_add` call, which ensures that `out_val` equals `lhs_val + rhs_val`. The `eval_fixed_add` function evaluates the addition operator at the fixed-point level in the NumerAIR library. If your implementation requires operating at the fixed-point level, please submit a PR to NumerAIR first. For non-linear functions, you should use look-up arguments instead of algebraic constraints. # Implementing the Operator Logic Now we need to implement the actual operator logic that will execute the addition and generate the trace. This is done by creating a new operator type and implementing the `LuminairOperator` trait. The `Add` operator is a primitive operator, so we will add this operator in `crates/graph/src/op/prim.rs`. ```rust theme={null} /// Implements element-wise addition for LuminAIR. #[derive(Debug, Clone, Default, PartialEq)] struct LuminairAdd {} impl LuminairOperator for LuminairAdd { /// Processes two input tensors, generating a trace, claim, and output tensor. fn process_trace( &mut self, inp: Vec<(InputTensor, ShapeTracker)>, table: &mut AddTraceTable, node_info: &NodeInfo, ) -> Vec { // Get buffer from tensor. let (lhs, rhs) = ( get_buffer_from_tensor(&inp[0].0), get_buffer_from_tensor(&inp[1].0), ); let lexpr = (inp[0].1.index_expression(), inp[0].1.valid_expression()); let rexpr = (inp[1].1.index_expression(), inp[1].1.valid_expression()); let mut stack: Vec = vec![]; let output_size = inp[0].1.n_elements().to_usize().unwrap(); // The actual output data initialized. let mut out_data = vec![Fixed::zero(); output_size]; let node_id: BaseField = node_info.id.into(); let lhs_id: BaseField = node_info.inputs[0].id.into(); let rhs_id: BaseField = node_info.inputs[1].id.into(); for (idx, out) in out_data.iter_mut().enumerate() { // Retrieves a value from data based on index expressions. // Evaluates index expressions to determine which element to access. // If the validity expression evaluates to non-zero, returns the element at the calculated index. // Otherwise, returns zero. let lhs_val = get_index(lhs, &lexpr, &mut stack, idx); let rhs_val = get_index(rhs, &rexpr, &mut stack, idx); // The actual addition. let out_val = lhs_val + rhs_val; // Calculate multiplicity values for the constraining the dataflow. let lhs_mult = if node_info.inputs[0].is_initializer { BaseField::zero() } else { -BaseField::one() }; let rhs_mult = if node_info.inputs[1].is_initializer { BaseField::zero() } else { -BaseField::one() }; let out_mult = if node_info.output.is_final_output { BaseField::zero() } else { BaseField::one() * BaseField::from_u32_unchecked(node_info.num_consumers) }; let is_last_idx: u32 = if idx == (output_size - 1) { 1 } else { 0 }; *out = out_val; // Add a row in the AddTraceTable. table.add_row(AddTraceTableRow { node_id, lhs_id, rhs_id, idx: idx.into(), is_last_idx: (is_last_idx).into(), next_idx: (idx + 1).into(), next_node_id: node_id, next_lhs_id: lhs_id, next_rhs_id: rhs_id, lhs: lhs_val.to_m31(), rhs: rhs_val.to_m31(), out: out_val.to_m31(), lhs_mult, rhs_mult, out_mult, }) } vec![Tensor::new(StwoData(Arc::new(out_data)))] } } ``` The operator logic: 1. Extracts input tensors and shape information. 2. Initializes the output tensor. 3. For each element in the output: * Retrieves the corresponding input elements. * Performs the addition. * Calculates multiplicity values for lookups. * Adds a row to the table with all necessary values. 4. Returns the computed output tensor. ## How the multiplicities are calculated? While each AIR component verifies its local operation, it is also important to ensure proper data flow between nodes in the computational graph. Specifically, the output of one node must match the input of another node. This consistency is enforced using the [LogUp](https://eprint.iacr.org/2022/1530?ref=blog.lambdaclass.com) lookup argument protocol, which establishes a system of relations between tensor values. **Output Yields** (Positive Multiplicity) * When a node produces an output that will be consumed by other nodes, its multiplicity equals the number of consumers. * This indicates that the value is “yielded” for use elsewhere in the graph. **Input Consumes** (Negative Multiplicity) * When a node receives an input from another node, its multiplicity is `-1`. * This signifies that the value is “consumed” by the operation. **Special Cases** (Zero Multiplicity) * Graph Inputs (Initializers): Tensors that serve as initial inputs to the graph have zero multiplicity because they are not consumed by any prior operation. * Graph Outputs (Final Results): Tensors that represent final outputs of the graph also have zero multiplicity since they are not yielded to subsequent operations. ## Generating the Interaction Trace The interaction trace is used for the LogUp argument, which is how different components in the system refer to each other's values. For the `Add` operator, we are defining the interaction trace in `crates/air/src/components/add/table.rs`. ```rust theme={null} /// Generates the interaction trace for the Add component using the main trace and lookup elements. pub fn interaction_trace_evaluation( main_trace_eval: &TraceEval, lookup_elements: &NodeElements, ) -> Result<(TraceEval, InteractionClaim), TraceError> { if main_trace_eval.is_empty() { return Err(TraceError::EmptyTrace); } let log_size = main_trace_eval[0].domain.log_size(); let mut logup_gen = LogupTraceGenerator::new(log_size); // Create trace for LHS let lhs_main_col = &main_trace_eval[AddColumn::Lhs.index()].data; let lhs_id_col = &main_trace_eval[AddColumn::LhsId.index()].data; let lhs_mult_col = &main_trace_eval[AddColumn::LhsMult.index()].data; let mut lhs_int_col = logup_gen.new_col(); for row in 0..1 << (log_size - LOG_N_LANES) { let lhs = lhs_main_col[row]; let id = lhs_id_col[row]; let multiplicity = lhs_mult_col[row]; lhs_int_col.write_frac( row, multiplicity.into(), lookup_elements.combine(&[lhs, id]), ); } lhs_int_col.finalize_col(); // Create trace for RHS let rhs_main_col = &main_trace_eval[AddColumn::Rhs.index()].data; let rhs_id_col = &main_trace_eval[AddColumn::RhsId.index()].data; let rhs_mult_col = &main_trace_eval[AddColumn::RhsMult.index()].data; let mut rhs_int_col = logup_gen.new_col(); for row in 0..1 << (log_size - LOG_N_LANES) { let rhs = rhs_main_col[row]; let id = rhs_id_col[row]; let multiplicity = rhs_mult_col[row]; rhs_int_col.write_frac( row, multiplicity.into(), lookup_elements.combine(&[rhs, id]), ); } rhs_int_col.finalize_col(); // Create trace for OUTPUT let out_main_col = &main_trace_eval[AddColumn::Out.index()].data; let node_id_col = &main_trace_eval[AddColumn::NodeId.index()].data; let out_mult_col = &main_trace_eval[AddColumn::OutMult.index()].data; let mut out_int_col = logup_gen.new_col(); for row in 0..1 << (log_size - LOG_N_LANES) { let out = out_main_col[row]; let id = node_id_col[row]; let multiplicity = out_mult_col[row]; out_int_col.write_frac( row, multiplicity.into(), lookup_elements.combine(&[out, id]), ); } out_int_col.finalize_col(); let (trace, claimed_sum) = logup_gen.finalize_last(); Ok((trace, InteractionClaim { claimed_sum })) } ``` The interaction trace generation: 1. Creates a new LogupTraceGenerator. 2. For each input and output column: * Creates a new column in the interaction trace. * For each row, writes a fraction with the value, ID, and multiplicity. * Finalizes the column. 3. Finalizes the entire trace and returns it along with the claimed sum. The lookup argument uses the concept of multiplicity to ensure that values are correctly used and produced. When a tensor element is used as input, it contributes a negative multiplicity. When a tensor element is produced as output, it contributes a positive multiplicity. The sum of multiplicities for each value should be zero, ensuring that each value is properly accounted for. ## Integrating with the Graph System To make your operator available in the graph system, you need to integrate it with the Luminal graph system. As `Add` operator is a primitive operator this is done in `crates/graph/src/op/prim.rs` by implementing the operator and adding it to the `PrimitiveCompiler`: ```rust theme={null} impl Compiler for PrimitiveCompiler { type Output = (); /// Compiles a graph by replacing Luminal operators with LuminAIR equivalents. fn compile(&self, graph: &mut Graph, mut ids: T) -> Self::Output { // Replace Luminal's ops with LuminAIR ops for id in graph.node_indices().collect::>() { let op = graph.node_weight(id).unwrap().as_any().type_id(); let op_ref = graph.graph.node_weight_mut(id).unwrap(); if let Some(c) = op_ref.as_any().downcast_ref::() { *op_ref = Box::new(LuminairConstant::new(c.0.clone())); } else if is::(op) { *op_ref = LuminairAdd::new().into_operator() } else if is::(op) { *op_ref = LuminairMul::new().into_operator() } else if is::(op) { *op_ref = Box::new(Contiguous) } } } } ``` # Adding the Operator to LuminAIR Claims and Components You also need to integrate the operator into the claim system and component infrastructure so that it can be properly included in proofs and verified. Let's expand on these important steps. ## Defining the Operator Claim Every operator needs a corresponding claim type that represents the operation in the proof system. First, in `crates/air/src/components/mod.rs`, you need to define a type alias for your operator's claim: ```rust theme={null} // For the Add operator pub type AddClaim = Claim; ``` This uses the generic Claim struct, which is defined as: ```rust theme={null} #[derive(Clone, Debug, Default, Eq, PartialEq, Serialize, Deserialize)] pub struct Claim { /// Logarithmic size (base 2) of the trace. pub log_size: u32, /// Phantom data to associate with the trace column type. _marker: std::marker::PhantomData, } ``` Then, you need to add your operator's claim type to the `ClaimType` enum, which is used to represent various types of claims in the system: ```rust theme={null} #[derive(Clone, Serialize, Deserialize, Debug)] pub enum ClaimType { Add(Claim), // We added the `Add` operator here Mul(Claim), } ``` ## Updating the LuminairClaim Struct The `LuminairClaim` struct in `crates/air/src/lib.rs` holds claims for all operators used in a computation. You need to update it to include your new operator: ```rust theme={null} #[derive(Serialize, Deserialize, Debug)] pub struct LuminairClaim { pub add: Option, // We added the `Add` operator's claim here pub mul: Option, pub is_first_log_sizes: Vec, } ``` Also update the `mix_into` method to include your new claim when computing the Fiat-Shamir challenge: ```rust theme={null} impl LuminairClaim { pub fn mix_into(&self, channel: &mut impl Channel) { if let Some(ref add) = self.add { add.mix_into(channel); } if let Some(ref mul) = self.mul { mul.mix_into(channel); } } } ``` And update the `log_sizes` method to include your operator's log sizes: ```rust theme={null} impl LuminairClaim { pub fn log_sizes(&self) -> TreeVec> { let mut log_sizes = vec![]; if let Some(ref add) = self.add { log_sizes.push(add.log_sizes()); } if let Some(ref mul) = self.mul { log_sizes.push(mul.log_sizes()); } } } ``` ## Updating the LuminairInteractionClaim Similarly, you need to update the `LuminairInteractionClaim` struct to include the claimed sum for your operator: ```rust theme={null} #[derive(Serialize, Deserialize, Default, Debug)] pub struct LuminairInteractionClaim { pub add: Option, pub mul: Option, } ``` And update its `mix_into` method: ```rust theme={null} impl LuminairInteractionClaim { pub fn mix_into(&self, channel: &mut impl Channel) { if let Some(ref add) = self.add { add.mix_into(channel); } if let Some(ref mul) = self.mul { mul.mix_into(channel); } } } ``` ## Integrating with LuminairComponents The LuminairComponents struct in `crates/air/src/components/mod.rs` needs to be updated to include your new operator component: ```rust theme={null} pub struct LuminairComponents { add: Option, mul: Option, } ``` Also update the `provers` methods to include your new component: ```rust theme={null} impl LuminairComponents { pub fn provers(&self) -> Vec<&dyn ComponentProver> { let mut components: Vec<&dyn ComponentProver> = vec![]; if let Some(ref add_component) = self.add { components.push(add_component); } if let Some(ref mul_component) = self.mul { components.push(mul_component); } components } } ``` ## Updating the OpCounter The `OpCounter` struct in `crates/air/src/pie.rs` tracks operation counts, so it should be updated: ```rust theme={null} #[derive(Serialize, Deserialize, Debug, Default)] pub struct OpCounter { pub add: Option, pub mul: Option, } ``` ## Updating the Graph System In the `LuminairGraph` trait implementation for `Graph` in `crates/graph/src/graph.rs`, you need to modify the `gen_trace` method to handle your new operator: ```rust theme={null} fn gen_trace(&mut self) -> Result { // Existing code... // Initialize trace collectors and tables let mut add_table: AddTraceTable = AddTraceTable::new(); let mut mul_table: MulTraceTable = MulTraceTable::new(); // Process nodes... for (node, src_ids) in self.linearized_graph.as_ref().unwrap() { let tensors = if as HasProcessTrace>::has_process_trace( node_op, ) { let tensors = as HasProcessTrace< AddColumn, AddTraceTable, >>::call_process_trace( node_op, srcs, &mut add_table, &node_info ) .unwrap(); *op_counter.add.get_or_insert(0) += 1; tensors } else if as HasProcessTrace>::has_process_trace( node_op, ) { // Existing code for Mul... } else { // Handle other operators or fallback node_op.process(srcs) } // Rest of the method... } // Convert tables to traces... if !add_table.table.is_empty() { let (trace, claim) = add_table.trace_evaluation()?; max_log_size = max_log_size.max(claim.log_size); traces.push(Trace::new( SerializableTrace::from(&trace), ClaimType::Add(claim), )); } if !mul_table.table.is_empty() { // Existing code for Mul... } // Return result... } ``` Additionally, you need to update the prove method to generate the interaction trace for your new operator: ```rust theme={null} fn prove( &mut self, pie: LuminairPie, ) -> Result, ProvingError> { // Existing code... // ┌───────────────────────────────────────┐ // │ Interaction Phase 1 - Main Trace │ // └───────────────────────────────────────┘ tracing::info!("Main Trace"); let mut tree_builder = commitment_scheme.tree_builder(); let mut main_claim = LuminairClaim::new(is_first_log_sizes.clone()); for trace in pie.traces.clone().into_iter() { // Add the components' trace evaluation to the commit tree. tree_builder.extend_evals(trace.eval.to_trace()); match trace.claim { ClaimType::Add(claim) => main_claim.add = Some(claim), ClaimType::Mul(claim) => main_claim.mul = Some(claim), } } // Mix the claim into the Fiat-Shamir channel. main_claim.mix_into(channel); // Commit the main trace. tree_builder.commit(channel); // ┌───────────────────────────────────────────────┐ // │ Interaction Phase 2 - Interaction Trace │ // └───────────────────────────────────────────────┘ // Draw interaction elements let interaction_elements = LuminairInteractionElements::draw(channel); // Generate the interaction trace from the main trace, and compute the logUp sum. let mut tree_builder = commitment_scheme.tree_builder(); let mut interaction_claim = LuminairInteractionClaim::default(); for trace in pie.traces.into_iter() { let claim = trace.claim; let trace: TraceEval = trace.eval.to_trace(); let lookup_elements = &interaction_elements.node_lookup_elements; match claim { ClaimType::Add(_) => { let (tr, cl) = add::table::interaction_trace_evaluation(&trace, lookup_elements).unwrap(); tree_builder.extend_evals(tr); interaction_claim.add = Some(cl); } ClaimType::Mul(_) => { let (tr, cl) = mul::table::interaction_trace_evaluation(&trace, lookup_elements).unwrap(); tree_builder.extend_evals(tr); interaction_claim.mul = Some(cl); } } } // Mix the interaction claim into the Fiat-Shamir channel. interaction_claim.mix_into(channel); // Commit the interaction trace. tree_builder.commit(channel); // Rest of the method... } ``` ## Checking Lookup Sum Validity In `crates/air/src/utils.rs`, update the `lookup_sum_valid` function to include your operator: ```rust theme={null} pub fn lookup_sum_valid(interaction_claim: &LuminairInteractionClaim) -> bool { let mut sum = PackedSecureField::zero(); if let Some(ref int_cl) = interaction_claim.add { sum += int_cl.claimed_sum.into(); } if let Some(ref int_cl) = interaction_claim.mul { sum += int_cl.claimed_sum.into(); } sum.is_zero() } ``` # Conclusion Congratulations! You've now learned how to implement a new operator in LuminAIR, using the `Add` operator as an example. By following this guide, you should be able to implement new operators for LuminAIR, extending its capabilities. # Contribution Guidelines Source: https://luminair.gizatech.xyz/contribute/guidelines Contribute to LuminAIR and be Rewarded. First of all, we sincerely appreciate your interest. It is precisely through contributions like yours that we can expand LuminAIR and build a robust and transparent AI ecosystem. # Getting Started Before you start contributing, please check the [Issue Tracker](https://github.com/gizatechxyz/LuminAIR/issues) to see if there are any existing issues that match what you're intending to do. If the issue doesn't exist, please create it. If you're creating a new issue, please provide a descriptive title and detailed description. If possible, include a code sample or an executable test case demonstrating the expected behavior that is not occurring. # Fork and Clone the Repository Once you've found an issue to work on, the next step is to fork the LuminAIR repo and clone it to your local machine. This is necessary because you probably won't have push access to the main repo. # Making Changes When you're ready to start coding, create a new branch on your cloned repo. It's important to use a separate branch for each issue you're working on. This keeps your changes separate in case you want to submit more than one contribution. Please use meaningful names for your branches. For example, if you're working on a bug with the softmax function, you might name your branch `fix-softmax-bug`. As you're making changes, make sure you follow the coding conventions used throughout the LuminAIR project. Consistent code style makes it easier for others to read and understand your code. # Submitting a Pull Request Once your changes are ready, commit them and push the branch to your forked repo on GitHub. Then you can open a pull request from your branch to the main branch of the LuminAIR repo. When you submit the pull request, please provide a clear, detailed description of the changes you've made. If you're addressing a specific issue, make sure you reference it in the description. Your pull request will be reviewed by the maintainers of the LuminAIR project. They may ask for changes or clarification on certain points. Please address their comments and commit any required changes to the same branch on your repo. # Running Tests Before you submit your pull request, you should run the test suite locally to make sure your changes haven't broken anything. Additionally, when you push your changes, the built-in Continuous Integration (CI) will also run all the tests on the pushed code. You can see the result of these tests in the GitHub interface of your pull request. If the tests fail, you'll need to revise your code and push it again. # Documentation We strive to provide comprehensive, up-to-date documentation for LuminAIR. If your changes require updates to the documentation, please include those in your pull request. Also, write Doc-Strings for the functions you implement. # Getting Rewarded LuminAIR contributions are rewarded through [OnlyDust](https://app.onlydust.com/projects/32e92e68-13a5-4859-a122-69c0e738a8d1/overview). It means that once the PR is merged you will be paid according to the time/difficulty of the PR or the priority of the feature implemented. # Benchmarks Source: https://luminair.gizatech.xyz/more/benchmarks Performance benchmarks for LuminAIR operations. # LuminAIR Performance Benchmarks This page shows the performance benchmarks for core LuminAIR operations, including trace generation, proof generation, and verification times. [Expend](https://gizatechxyz.github.io/LuminAIR/bench/)